
Linearising exponential and power data
By MathLab · Reviewed
Linearising data means transforming variables so that a proposed nonlinear relationship becomes a straight-line relationship. A straight line is easier to recognise and analyse because its gradient and intercept reveal the parameters of the original model.
The two central results are
and
They look similar, but require different graphs. For an exponential model, plot against . For a power model, plot against .
Which graph should you plot?
Section titled “Which graph should you plot?”| Proposed model | Linear form | Horizontal axis | Vertical axis | Gradient | Intercept |
|---|---|---|---|---|---|
The phrase plot against means put on the vertical axis and on the horizontal axis.
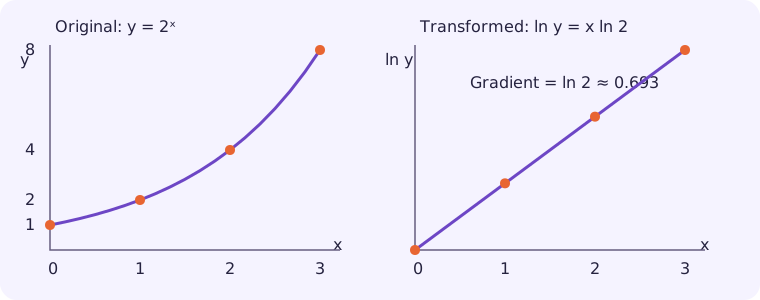
The same four observations appear on both graphs. Transforming the vertical coordinate changes the curve into a line; it does not change the original measurements.
Before you begin
Section titled “Before you begin”You should be able to:
- use exponential functions;
- apply the laws of logarithms;
- interpret the gradient and intercept in the equation of a straight line;
- use a calculator to find logarithms and perform linear regression.
Why linearisation works
Section titled “Why linearisation works”A straight line has the form
where is the horizontal variable, is the vertical variable, is the gradient and is the vertical intercept.
Linearisation does not claim that the original graph of against is straight. It defines transformed variables and so that the transformed equation has the form .
The comparison with should always be explicit. It prevents the most common error: reading the correct gradient from the wrong axes.
Exponential models
Section titled “Exponential models”Suppose
where , and . Taking natural logarithms gives
Rearrange this as
Therefore a plot of on the vertical axis against on the horizontal axis should be a straight line with
Recover the original parameters by undoing the logarithms:
If the original model is written as , then
so the gradient is directly .
Worked example 1: transform an equation
Section titled “Worked example 1: transform an equation”The variables and are believed to satisfy
Find the equation of the straight line obtained by plotting against .
Take natural logarithms:
Hence the straight-line equation is
The gradient is positive because , so the original model represents growth.
Worked example 2: recover an exponential model
Section titled “Worked example 2: recover an exponential model”A plot of against produces the line
Write the relationship between and in the forms and .
Exponentiate both sides:
Therefore
so, to three significant figures,
For the form ,
giving
The negative gradient means , which is consistent with exponential decay.
Worked example 3: linearise a table of data
Section titled “Worked example 3: linearise a table of data”The following measurements are believed to follow .
Add a row of transformed values, keeping enough decimal places for the calculation:
The increments in are approximately constant for equal increments in , so a plot of against is approximately linear.
Using the first and last transformed points,
The intercept is approximately , so
The model is therefore
With real data, use all the transformed points in a linear regression rather than estimating from two arbitrarily chosen data points.
Power models
Section titled “Power models”Suppose
where and, for logarithms, and . Taking natural logarithms gives
Now compare with :
Therefore a plot of against should be a straight line with
The gradient is the power itself. This is the key distinction from an exponential model.
Worked example 4: recover a power model
Section titled “Worked example 4: recover a power model”A plot of against has gradient and vertical intercept . Find the model .
Since the gradient equals ,
Since the intercept equals ,
and therefore
Thus
Do not set . The intercept is , not .
Worked example 5: use two transformed points
Section titled “Worked example 5: use two transformed points”Variables and satisfy . On a graph of against , the straight line passes through and . Find and .
The gradient is
The intercept is
so
Therefore
This example uses base rather than base . The method is unchanged, but the inverse operation must match the logarithm used: for common logarithms and for natural logarithms.
Worked example 6: build and use a model
Section titled “Worked example 6: build and use a model”For a particular material, breaking load is modelled by , where is diameter. A log-log regression gives
Find the model and estimate when .
Comparing with
gives
Hence
At ,
Therefore
in the stated units. Use the unrounded values of and in the final calculation if they are available.
A useful diagnostic
Section titled “A useful diagnostic”If both an exponential and a power model seem plausible:
- plot against to test an exponential model;
- plot against to test a power model;
- compare the patterns of residuals and the strength of the linear fits;
- use the context and mechanism, not correlation alone, to select a model.
A high correlation coefficient for transformed data supports linearity over the observed range. It does not prove that the proposed law is true for all values.
Using regression carefully
Section titled “Using regression carefully”For transformed data, enter the appropriate transformed variables into two calculator lists and perform linear regression in the form
Calculator letters vary, so translate the output by meaning:
- is the gradient;
- is the vertical intercept;
- the original parameters follow from the comparison table above.
Record more digits than the final answer requires. Premature rounding of logarithms, gradients or intercepts can noticeably change the recovered model.
If a question asks you to draw a line of best fit by hand, choose two well-separated points on the line, not necessarily two measured data points. Then calculate
Widely separated points reduce the effect of reading error.
Domain, units and limitations
Section titled “Domain, units and limitations”Logarithms require positive inputs
Section titled “Logarithms require positive inputs”To calculate and as real numbers, both and must be positive. Zero and negative observations cannot simply be included in a logarithmic transformation.
This does not automatically mean the underlying situation is impossible. It means that this particular transformation and model need reconsideration. A shifted model such as does not become linear merely by plotting against because
Logs and dimensional quantities
Section titled “Logs and dimensional quantities”Strictly, a logarithm acts on a dimensionless ratio. In a data analysis, writing is shorthand for logging the numerical value of in fixed stated units, or for using a reference value .
Changing units can alter the intercept, and sometimes the numerical value of , but it does not alter the essential fitted relationship when conversions are handled consistently. Always state the units of the original variables and use one unit system throughout.
Transformation changes the error structure
Section titled “Transformation changes the error structure”Least-squares regression on minimises vertical discrepancies in , not in . It is therefore especially natural when errors are proportional or multiplicative. A good transformed fit should still be checked against the original data and context.
Interpolation and extrapolation
Section titled “Interpolation and extrapolation”An estimate within the observed range is an interpolation. An estimate beyond it is an extrapolation and is less reliable. Linear appearance after transformation does not justify extreme predictions.
Common misconceptions
Section titled “Common misconceptions””Taking logs makes any curve straight”
Section titled “”Taking logs makes any curve straight””No. It makes particular model families straight. If the proposed model is unsuitable, the transformed points will still show curvature or another systematic pattern.
”The gradient of against is the base”
Section titled “”The gradient of lny\ln ylny against xxx is the base””For , the gradient is , so . The gradient is directly the exponent coefficient only when the model is written .
”A power model needs only the values logged”
Section titled “”A power model needs only the yyy values logged””For , both variables must be logged:
Plotting against tests an exponential model instead.
”The intercept is ”
Section titled “”The intercept is AAA””For both principal transformations, the intercept is . Exponentiate it to recover .
”The base of the logarithm changes the power”
Section titled “”The base of the logarithm changes the power””It does not. For a power model, the gradient is with any consistent logarithm base. Only the interpretation of the intercept changes from to , for example.
Self-check
Section titled “Self-check”1. Identify the axes
Section titled “1. Identify the axes”Which graph should be linear if ?
Answer
Plot vertically against horizontally. The line has gradient and intercept .
2. Recover an exponential model
Section titled “2. Recover an exponential model”A plot of against has gradient and intercept . Find the model in the form .
Answer
Therefore
3. Recover a power model
Section titled “3. Recover a power model”A plot of against has equation
Find and in .
Answer
The gradient gives . The intercept gives
so
Thus .
4. Spot the error
Section titled “4. Spot the error”A student linearises and writes . What has gone wrong?
Answer
They have treated as . The correct transformation is
5. Interpret the evidence
Section titled “5. Interpret the evidence”The correlation coefficient between and is . What does this suggest, and what does it not prove?
Answer
It suggests that an exponential decay model may fit the observed range very well because is strongly and negatively linearly related to . It does not prove causation, establish the mechanism, or guarantee reliable extrapolation outside the data range.
Exam checklist
Section titled “Exam checklist”Before finishing a linearisation question, check that you have:
- taken logarithms of the complete model;
- expanded them using the log laws correctly;
- identified the transformed and variables;
- compared the equation explicitly with ;
- interpreted the gradient and intercept for the stated model;
- undone the logarithm using the matching base;
- kept unrounded calculator values until the final answer;
- stated the final model in the requested form;
- commented on fit and extrapolation only as strongly as the evidence allows.
Next steps
Section titled “Next steps”- Use these models in exponential growth and decay.
- Practise solving for unknown inputs in exponential and logarithmic equations.
- Develop model selection and validation in functions in modelling.
- Review how to interpret conclusions in context in interpreting context.